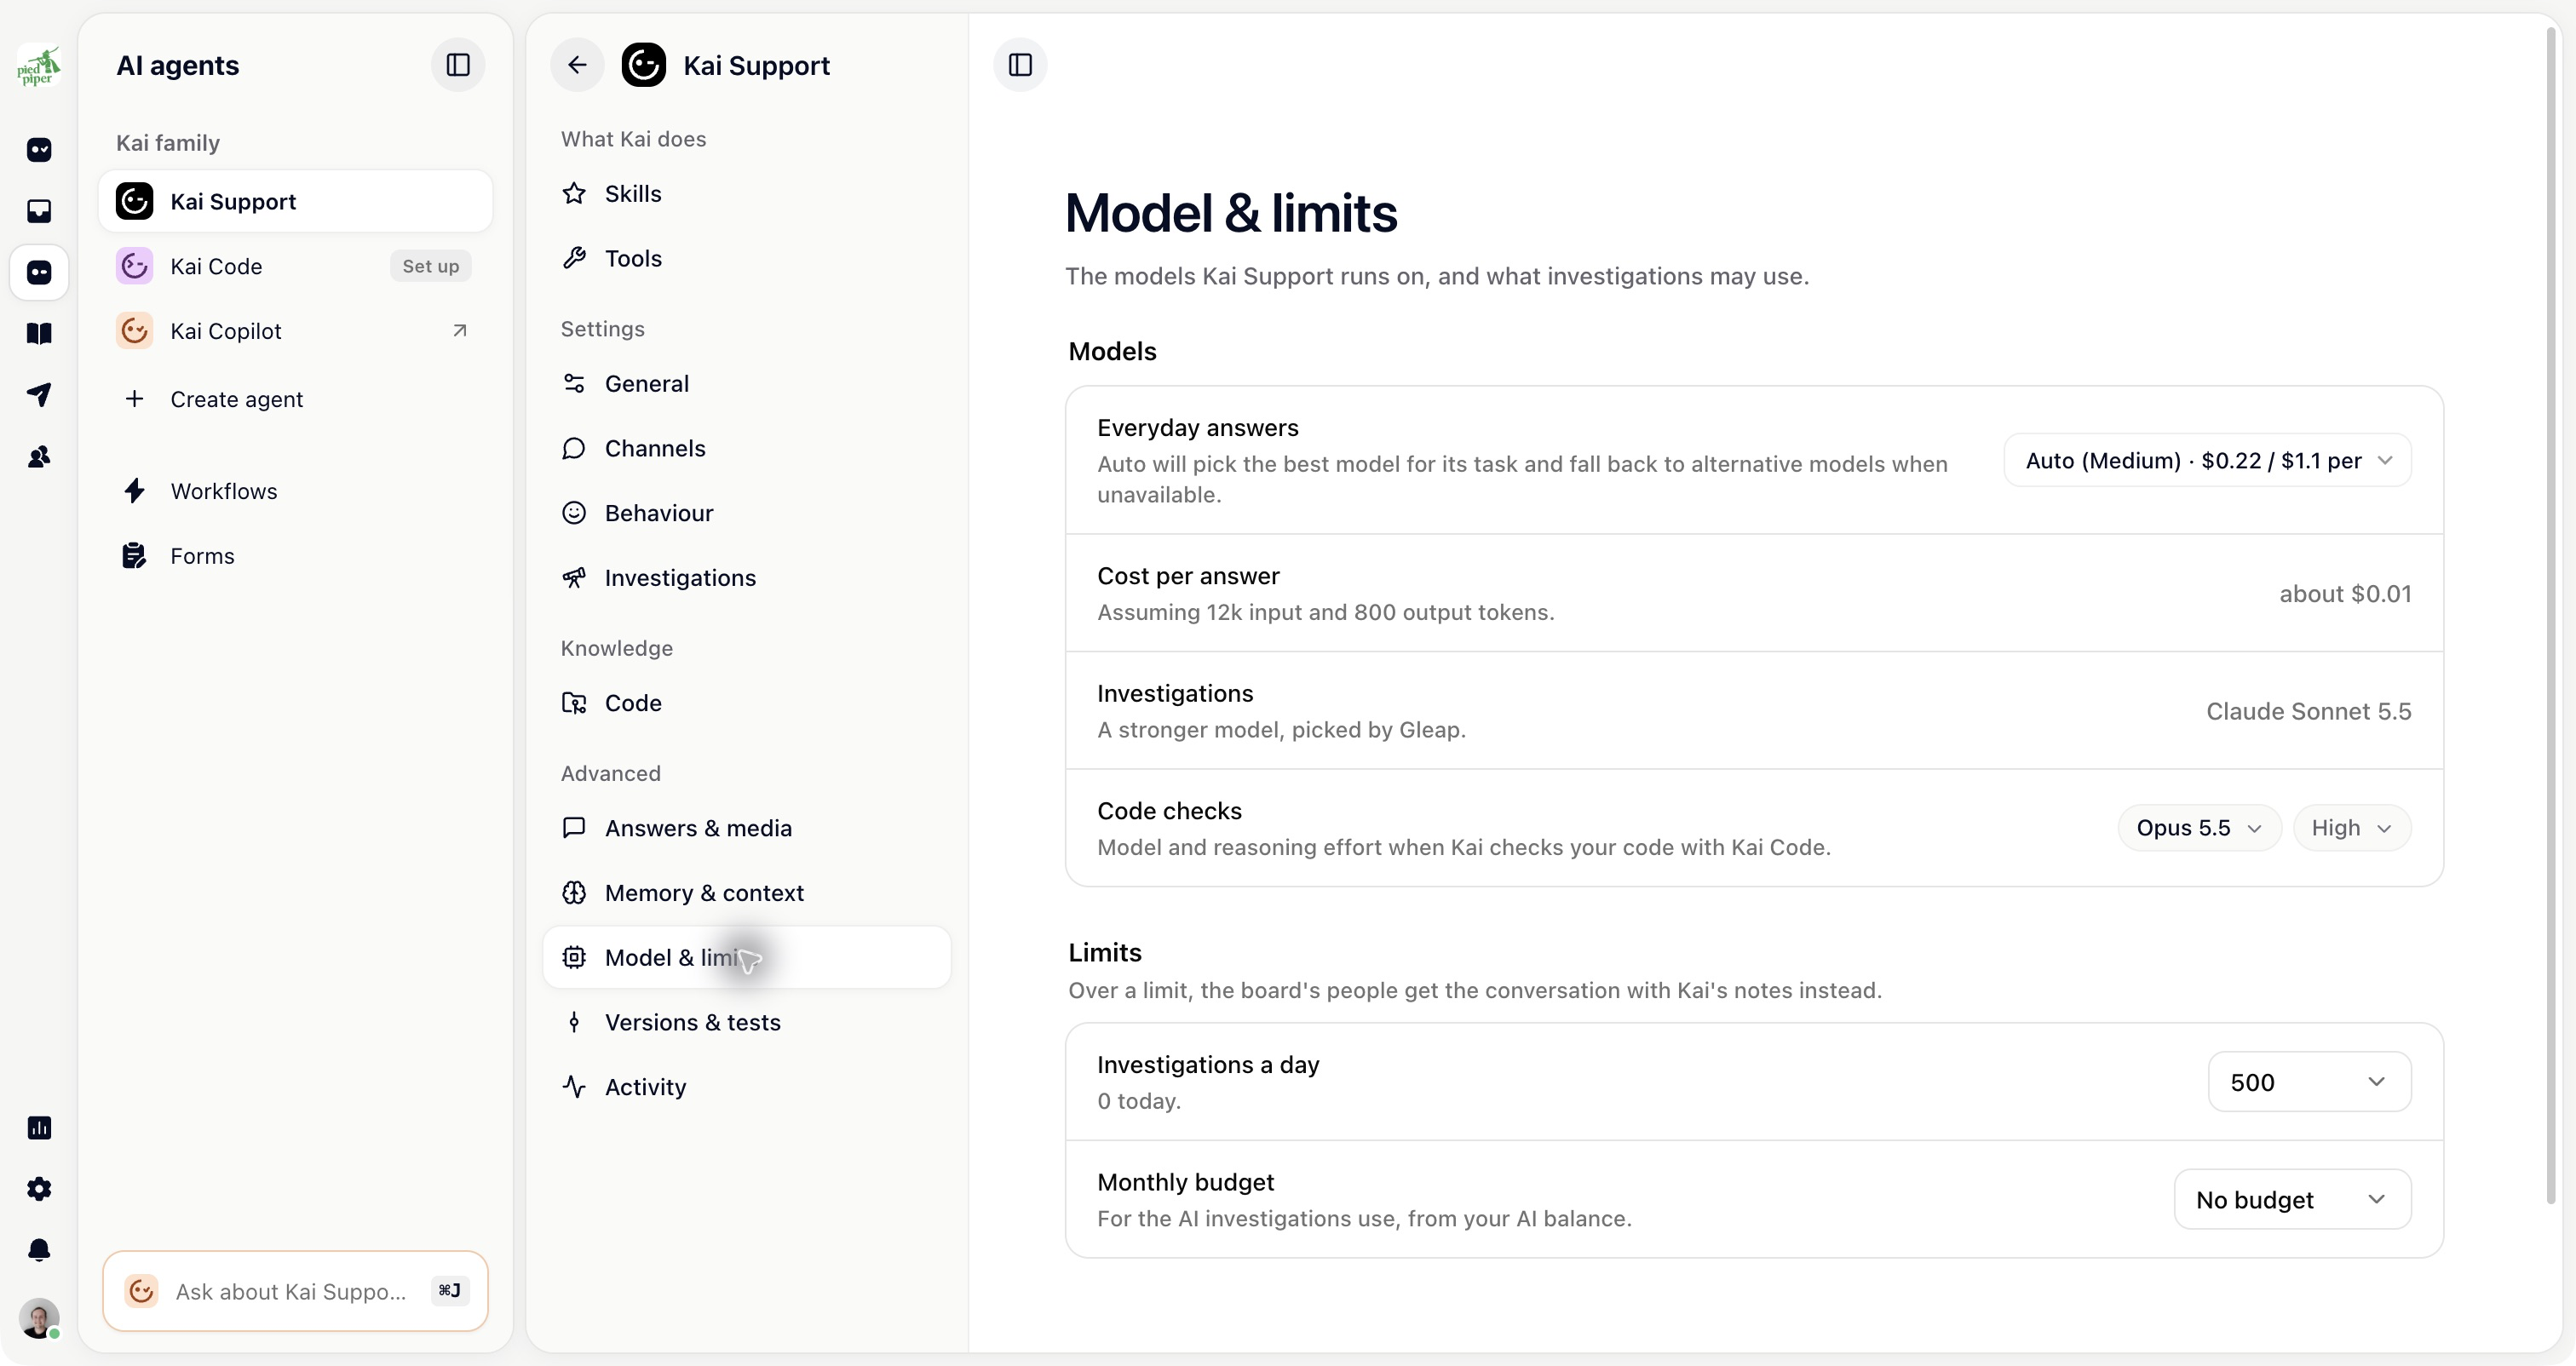
Kai Support's model is set under AI agents → Kai Support → Settings → Model & limits. What you see there depends on your plan.
On plans without model selection, Picked by Gleap means Gleap chooses the model. Current Kai Support billing follows AI usage. Older workspaces can retain per-resolution or included-AI terms; check Billing for the mode your workspace uses. The investigation model is configured separately where your plan allows it.
Auto picks a model for the task and falls back to another when one isn't available. That fallback is the main reason to leave it alone: a provider outage doesn't stop Kai from answering.
On older plans without model selection, the row reads Auto routing and can't be changed. The Unlock button next to it shows what's needed.
Open AI agents → Kai Support → Settings → Model & limits.
Open the dropdown. Each entry shows its price per million tokens, input and output.
Pick a model. Below the dropdown you see a short description of it and Cost per answer.
Compare models by Cost per answer, an estimate for about 12,000 input and 800 output tokens. It's closer to what a real conversation costs than the per-million rates.
Gleap maintains the list and updates it as models are released and retired. If a model you pinned later leaves the list, your choice keeps working and stays visible in the dropdown, so nothing breaks silently and you can move to a current model when you're ready.
How the answer reads: phrasing, and how well it holds a longer thread together.
How it handles a question that needs several pieces of your documentation combined.
Cost per answer, which varies widely across the list.
Whether customers can send screenshots. Not every model reads images. If yours can't, the Images switch under Answers & media is disabled and names the model.

Start on Auto and change it only when you have a reason. The usual one is cost, once you can see what you spend per answer. If your customers often send screenshots, check that the model you pin reads images.
After a change, read a handful of real conversations. Model behaviour on your own content is hard to predict from a description, and the difference usually shows on questions your documentation only partly covers.